Posts
- 28th September 2026
-
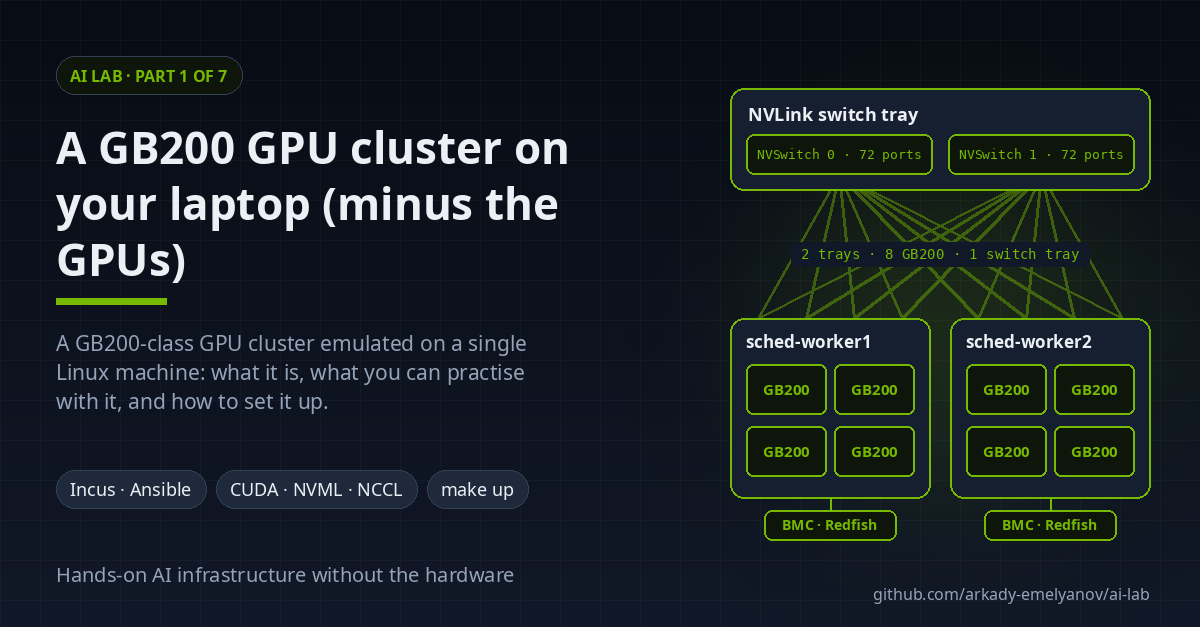
AI lab, part 1: a GB200 GPU cluster on your laptop (minus the GPUs)
A GB200-class GPU cluster emulated on a single Linux machine: what it is, what you can practise with it, and how to set it up.
- 29th September 2026
-
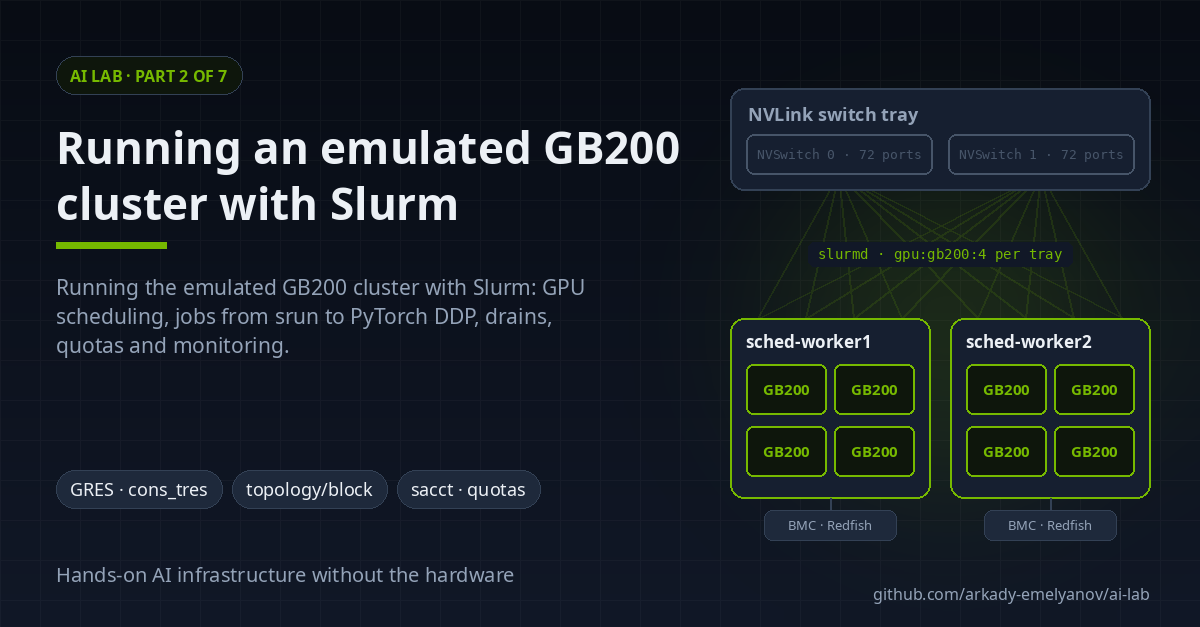
AI lab, part 2: running an emulated GB200 cluster with Slurm
Running the emulated GB200 cluster with Slurm: GPU scheduling, jobs from srun to PyTorch DDP, drains, quotas and monitoring.
- 30th September 2026
-
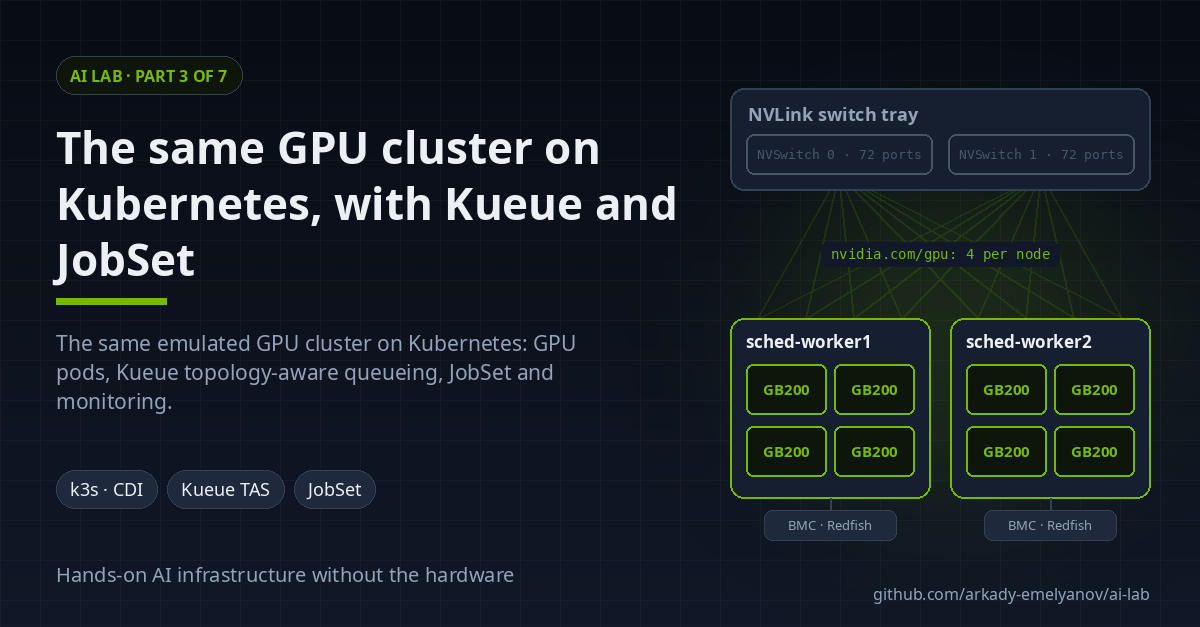
AI lab, part 3: the same GPU cluster on Kubernetes, with Kueue and JobSet
The same emulated GPU cluster on Kubernetes: GPU pods, Kueue topology-aware queueing, JobSet and monitoring.
- 1st October 2026
-
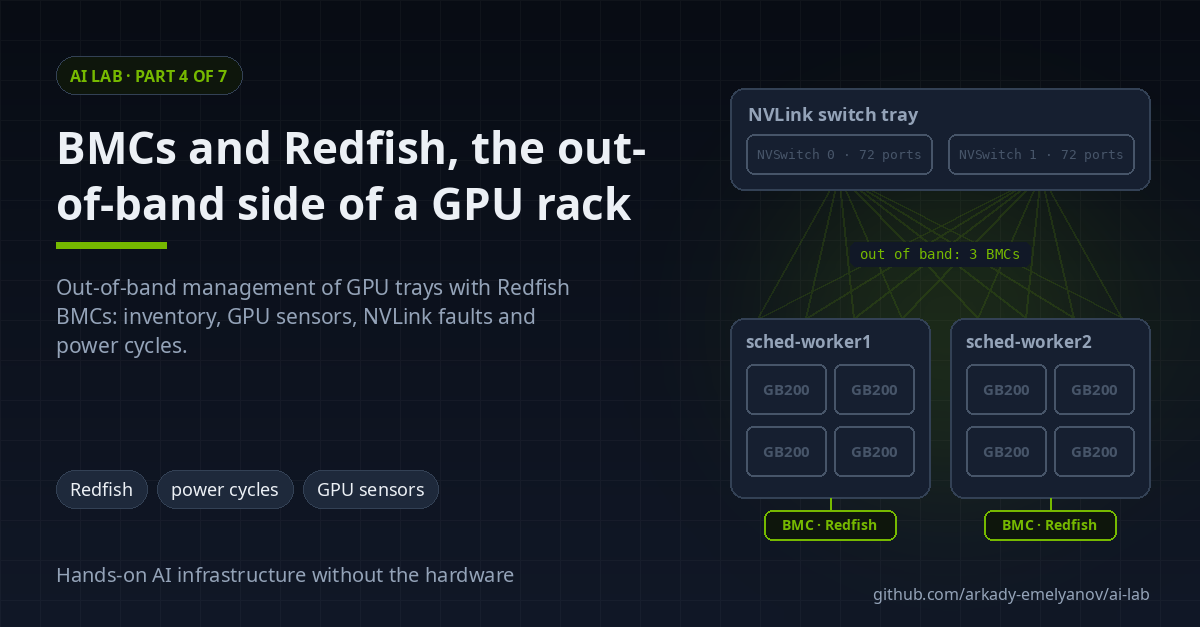
AI lab, part 4: BMCs and Redfish, the out-of-band side of a GPU rack
Out-of-band management of GPU trays with Redfish BMCs: inventory, GPU sensors, NVLink faults and power cycles.
- 2nd October 2026
-
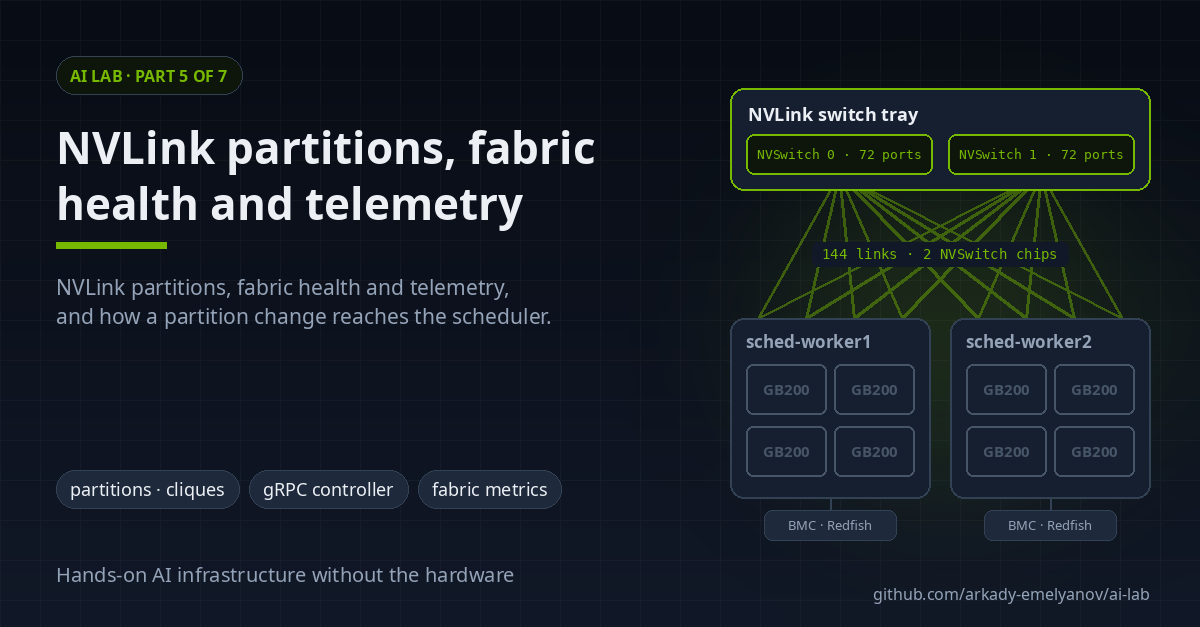
AI lab, part 5: NVLink partitions, fabric health and telemetry
NVLink partitions, fabric health and telemetry, and how a partition change reaches the scheduler.
- 3rd October 2026
-
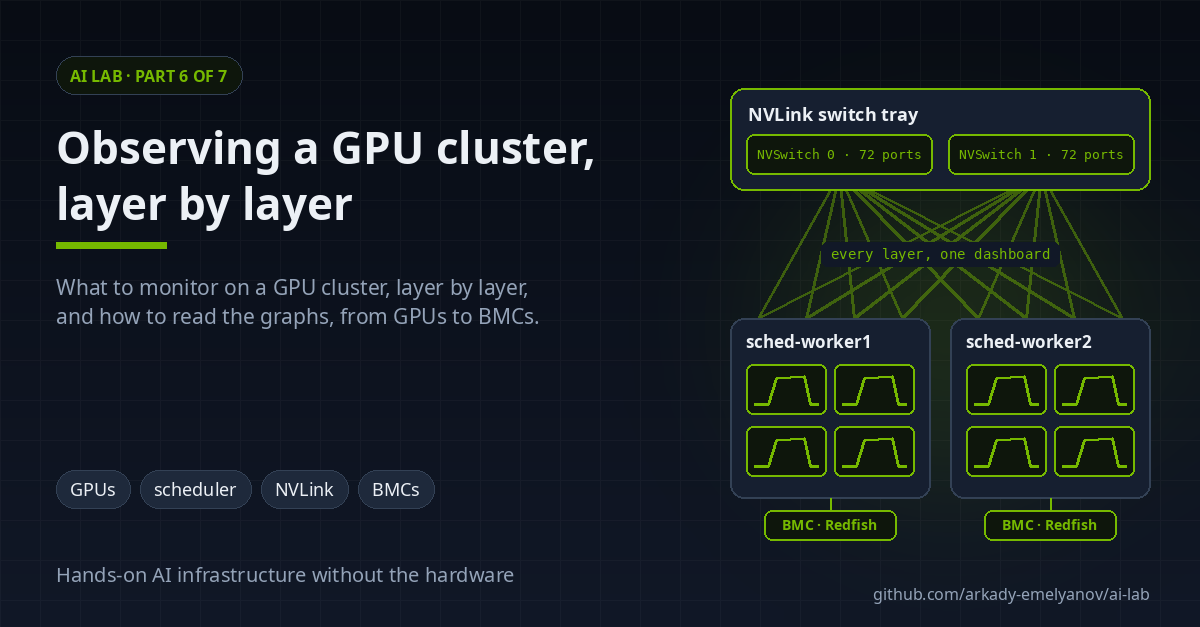
AI lab, part 6: observing a GPU cluster, layer by layer
What to monitor on a GPU cluster, layer by layer, and how to read the graphs, from GPUs to BMCs.
- 3rd October 2026
-
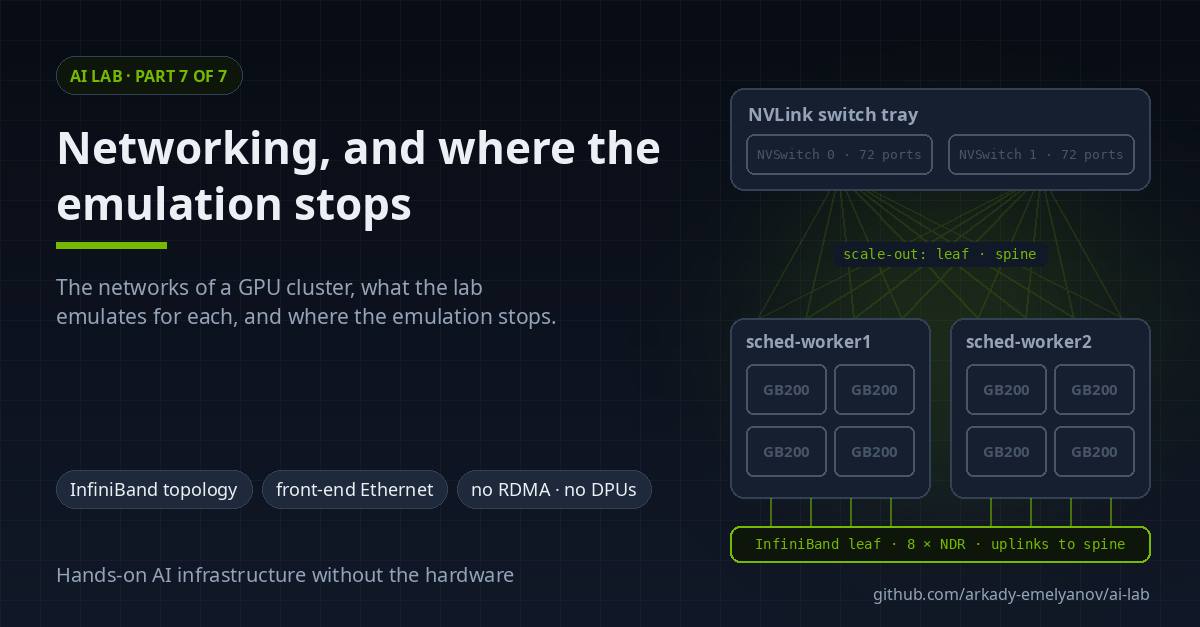
AI lab, part 7: networking, and where the emulation stops
The networks of a GPU cluster, what the lab emulates for each, and where the emulation stops.